Tensor Cores
How NVIDIA Tensor Cores work, from the first FP16 units in Volta to FP4 in Blackwell: matrix multiply-accumulate, precision and throughput explained.
Tensor Cores, explained from first principles
Tensor Cores are the matrix-multiply engines inside NVIDIA GPUs and the main reason a modern GPU can train and run AI models. This section explains what they compute, how each generation from Volta to Blackwell changed them, and how number formats such as FP16, FP8 and FP4 make them faster.
New to the topic? Read the guides below in order. Each one builds on the last and links to tools that let you try the numbers yourself.
Start here
Tools for this topic
Edited by Sami Ullah Khan. Read our editorial policy.
All Tensor Cores articles
2:4 Structured Sparsity Explained: How Sparse Tensor Cores Double AI Throughput
What 2:4 structured sparsity is, how NVIDIA and AMD tensor cores use it to skip half the math, why spec sheets list "with sparsity"…

Mixed Precision Training Explained: FP16, BF16 and FP8 on Tensor Cores
How mixed precision training works, why it makes training up to several times faster on tensor cores, the difference between FP16 with loss scaling…
What Is DLSS? How Tensor Cores Power AI Upscaling and Frame Generation
DLSS uses AI models running on Tensor Cores to upscale games, generate extra frames and clean up ray tracing. Every version from DLSS 1…
Tensor Cores vs RT Cores: What Each Does in an RTX GPU
Tensor Cores do matrix math for AI and DLSS; RT Cores trace rays for lighting and reflections; CUDA cores handle everything else. How the…
TOPS vs TFLOPS: How to Compare AI Chip Performance Numbers
TOPS and TFLOPS both count trillions of operations per second, but vendors quote them at different precisions, with or without sparsity. How to convert…
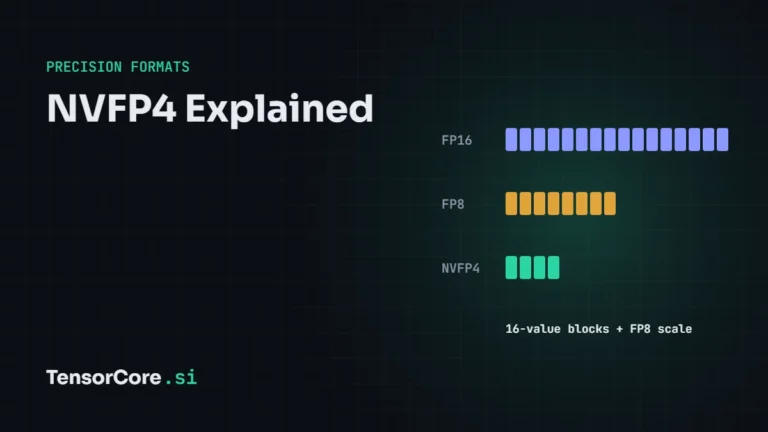
NVFP4 Explained: NVIDIA's 4-Bit Format for Blackwell
NVFP4 stores values in FP4 E2M1 with an FP8 scale per 16 values and an FP32 tensor scale. How it works, NVFP4 vs MXFP4,…
What Is a Tensor Core? A Plain-Language Guide
A Tensor Core is the matrix-math engine inside NVIDIA GPUs. Here is what it computes, why AI depends on it, and how it went…
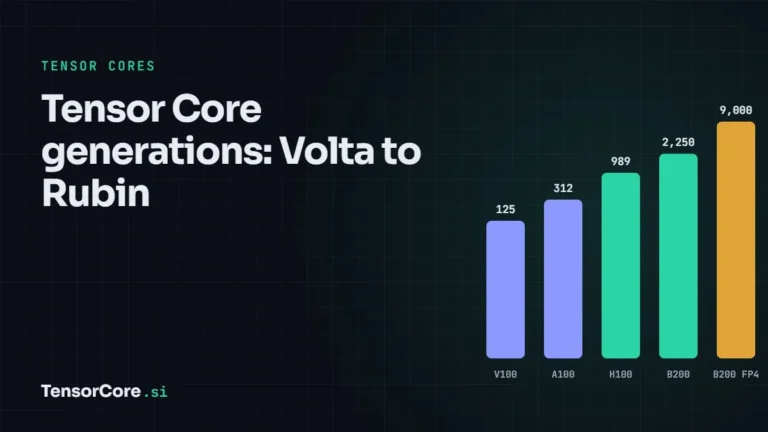
Tensor Core Generations: From Volta to Blackwell and Rubin
Every NVIDIA Tensor Core generation from 2017 to 2026: the GPUs, the new number formats, the peak throughput and the one big idea each…
Hopper vs Blackwell: What Changed for AI
H100 and H200 against B200 and B300: memory, bandwidth, FP8 and FP4 throughput, NVLink, and what the differences mean for training and for serving…
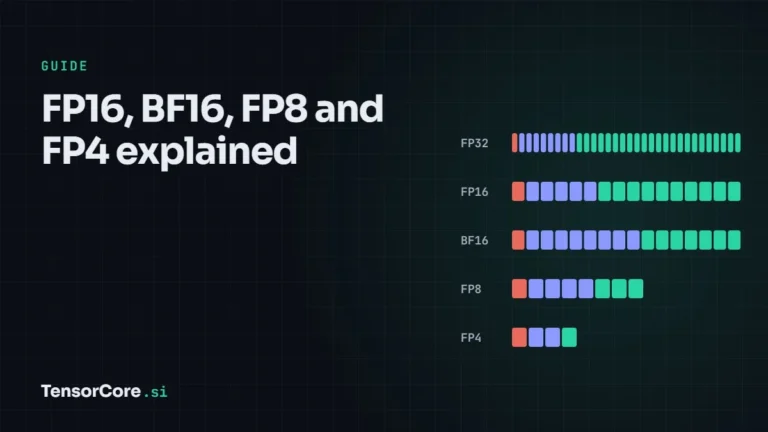
FP16, BF16, FP8 and FP4: Precision Formats Explained
Why AI runs on 16-, 8- and even 4-bit numbers, how each format trades range for precision, and what microscaling, NVFP4 and FP32 accumulation…