Guides
Plain-language guides to AI hardware concepts: precision formats, quantization, sparsity, FLOPS and how to read a GPU spec sheet.
Practical guides for choosing and using AI hardware
Guides for people choosing, buying or using AI hardware: which GPU runs which model, how much memory you need, what training costs, and how to read the performance numbers vendors publish.
Running models at home? Start with the first three. Planning training or comparing chips? Jump to the cost and TOPS guides.
Start here
Tools for this topic
Edited by Sami Ullah Khan. Read our editorial policy.
All Guides articles
Prefill vs Decode: How LLM Inference Runs on a GPU
Every LLM response has two phases: prefill reads the whole prompt at once and is limited by compute; decode generates one token at a…
How Much Does It Cost to Train an LLM? Compute, GPU-Hours and Real Examples
Training an LLM costs about 6 × parameters × tokens in compute. How to turn that into GPU-hours and dollars, worked examples from 7B…
GPU vs CPU for AI: Why GPUs Run Machine Learning
Why AI runs on GPUs instead of CPUs: thousands of parallel cores, Tensor Cores and much faster memory. A side-by-side comparison, real numbers, and…
What Is CUDA? NVIDIA's GPU Computing Platform Explained
CUDA is NVIDIA's platform for running general programs on its GPUs. What it includes, how kernels, threads and warps work, why every AI framework…
TOPS vs TFLOPS: How to Compare AI Chip Performance Numbers
TOPS and TFLOPS both count trillions of operations per second, but vendors quote them at different precisions, with or without sparsity. How to convert…
RTX 5090 for AI: Which LLMs It Runs, How Fast, and Is It Worth It?
The RTX 5090 has 32 GB of GDDR7 at 1.79 TB/s and fifth-generation Tensor Cores with FP4. Which local LLMs and image models fit,…
NPU vs GPU vs TPU: What Is an NPU and How Is It Different?
An NPU is a small, power-efficient AI accelerator inside phone and laptop chips. How NPUs compare with GPUs and TPUs in design, TOPS, memory…
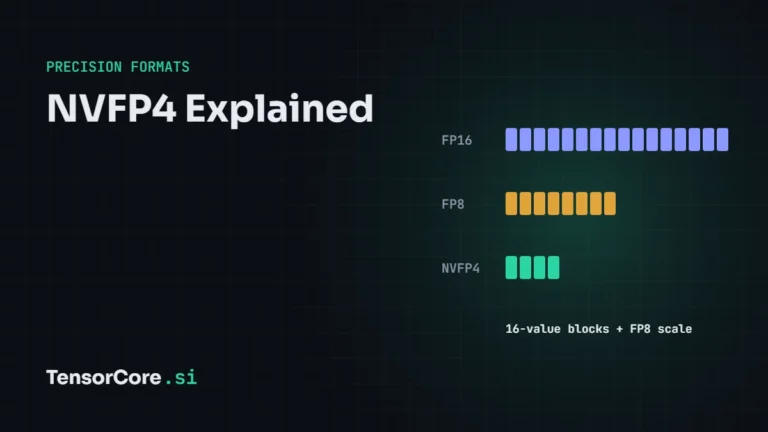
NVFP4 Explained: NVIDIA's 4-Bit Format for Blackwell
NVFP4 stores values in FP4 E2M1 with an FP8 scale per 16 values and an FP32 tensor scale. How it works, NVFP4 vs MXFP4,…
NVIDIA DGX Spark Explained: Specs, LLM Speed and Who It Is For
DGX Spark packs a GB10 Grace Blackwell chip and 128 GB of unified memory into a mini PC. Specs, which models fit, real LLM…
LLM Quantization Explained: GGUF, GPTQ, AWQ, FP8 and FP4
How quantization shrinks models to 4 bits, what GGUF Q4_K_M, GPTQ, AWQ, NF4, FP8 and FP4 mean, which to use, and how much quality…