TensorCore.si Blog
Tensor Cores, GPUs and AI chips, explained
In-depth guides, generation-by-generation breakdowns and analysis of the hardware that trains and runs modern AI.
NVIDIA DGX Spark Explained: Specs, LLM Speed and Who It Is For
DGX Spark packs a GB10 Grace Blackwell chip and 128 GB of unified memory into a mini PC. Specs, which models fit, real LLM…
TPU vs GPU: What Is the Difference for AI? (2026)
TPUs are Google's systolic-array AI chips; GPUs are general-purpose with Tensor Cores. Architecture, Ironwood vs B200 specs, scaling, software and which to choose.
LLM Quantization Explained: GGUF, GPTQ, AWQ, FP8 and FP4
How quantization shrinks models to 4 bits, what GGUF Q4_K_M, GPTQ, AWQ, NF4, FP8 and FP4 mean, which to use, and how much quality…
KV Cache Explained: Why Long Context Uses So Much Memory
The KV cache stores keys and values for every past token. The formula, sizes for Llama, Qwen and DeepSeek, GQA vs MLA, and how…
Best GPU for Running LLMs Locally (2026 Guide)
VRAM decides which models you can run and bandwidth decides speed. GPUs and Macs compared for Llama, Qwen, DeepSeek and gpt-oss, with VRAM needs…
How to Read a GPU Spec Sheet: TFLOPS, Sparsity and Memory
Dense vs sparse TFLOPS, per-GPU vs per-server figures, SXM vs PCIe, memory bandwidth, the peak FLOPS formula and how to estimate real training time…
NVLink and NVSwitch Explained: How AI GPUs Talk to Each Other
NVLink connects GPUs at up to 1.8 TB/s and NVSwitch lets 8 to 72 GPUs talk at full speed. Generations, NVL72, all-reduce math and…
What Is HBM? High Bandwidth Memory for AI GPUs Explained
HBM stacks DRAM dies beside the GPU on a 1,024-bit bus per stack. Learn how it works, every generation from HBM2 to HBM4, and…
What Is a Tensor Core? A Plain-Language Guide
A Tensor Core is the matrix-math engine inside NVIDIA GPUs. Here is what it computes, why AI depends on it, and how it went…
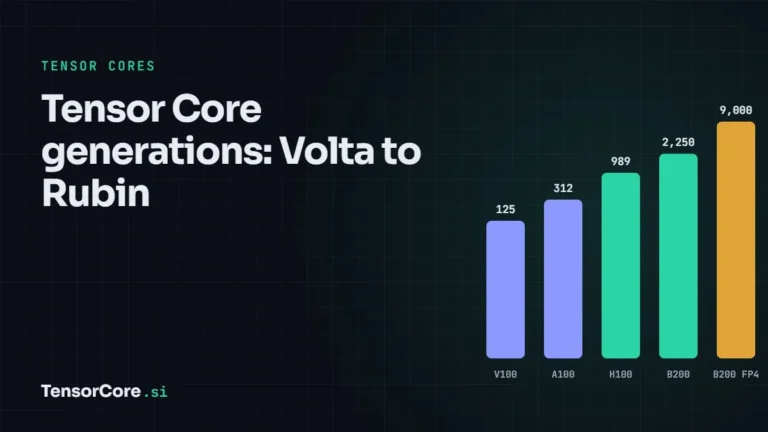
Tensor Core Generations: From Volta to Blackwell and Rubin
Every NVIDIA Tensor Core generation from 2017 to 2026: the GPUs, the new number formats, the peak throughput and the one big idea each…